


Benchmarks
5 min
Nanbeige4.3-33B: agent benchmark results
The card updated on October 25 compares four models on agent tests, with results from the Nanbeige team itself and limitations in the evaluation.
#Nanbeige#Nanbeige4.3-33B#benchmarks
252 artigos por Marcelo Santiago
The card updated on October 25 compares four models on agent tests, with results from the Nanbeige team itself and limitations in the evaluation.
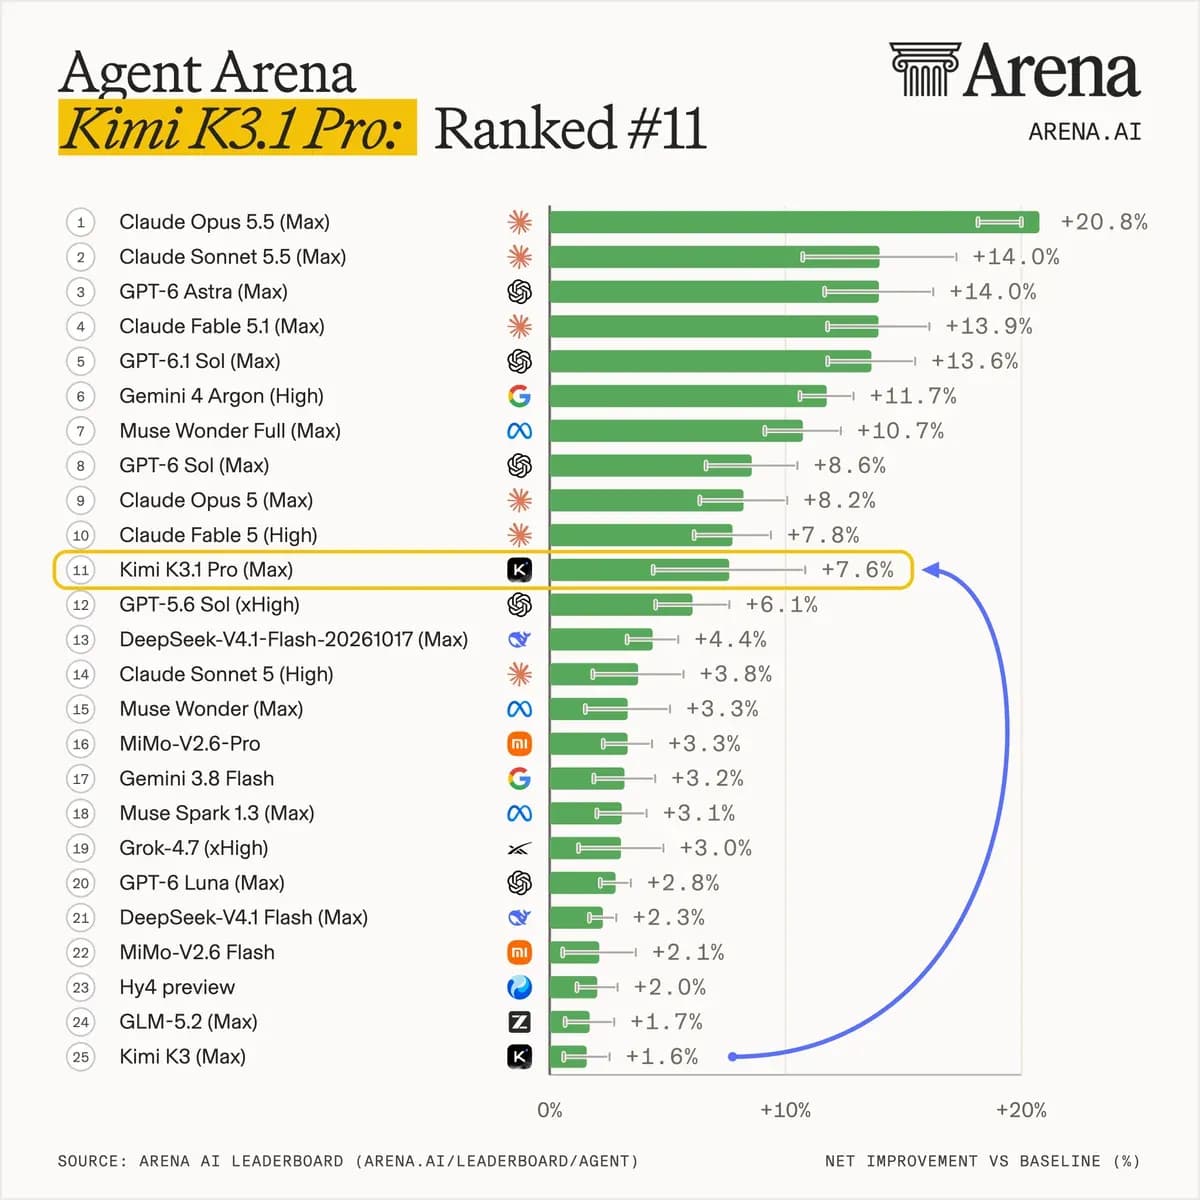
Arena added Kimi K3.1 Pro to Agent Arena on October 24. The chart shows the model in 11th place, with +7.6% versus baseline.
AtMem 2.3.10 separates evidence discovery from context injection. The reported DolphinBench result (390/600) and what the evaluation does not prove.

Qwen Code 0.26.1 adds qwen daemon start --save-token, context compression for idle sessions and session isolation fixes. Here is how to use them.
What's new in Claude Code 2.1.310: the Monitor tool, plugin monitors on Bedrock, Vertex and Foundry, and the session and permission fixes to know about.
OpenAI found unauthenticated remote code execution in the Brotli decoder. See which software ships it (Node.js, Bun, Envoy), how to check exposure and how to patch.
The GitHub Copilot API now breaks down requests and tokens by client, including OpenCode, in daily and 28 day reports.
Anthropic explained how Claude Duet combines approvals, external checks beyond the model and isolated credentials before acting on connected services.

Google Cloud has launched an Anthropic-managed deployment option for Claude, with day zero access to Claude Platform features.

Joint analysis by Anthropic and UK AISI on a previous test records out-of-scope actions in 9 of 43 cybersecurity runs.
Anthropic reports using Claude and Rocq to verify 123 C and C++ libraries, covering 239 entry points in a security program.
Moonshot reports 65.7% for Kimi K3.1 Pro on Terminal-Bench 4.0, close to Claude Opus 5.5, in a test released by the company itself.
In-depth technical curation: agentic architectures, real token benchmarks, MCP servers and open-source tools in your inbox and on the blog.