
Which model performs better on long coding tasks? In Terminal-Bench 4.0, Moonshot reports 65.7% for Kimi K3.1 Pro and 66.4% for Claude Opus 5.5. The result was published on October 23, 2026; the page does not list the time.
Kimi K3.1 Pro scores 65.7% on Terminal-Bench 4.0
Moonshot reports 65.7% for Kimi K3.1 Pro on Terminal-Bench 4.0, close to Claude Opus 5.5, in a test released by the company itself.

Marcelo Santiago
Criador do bridgecode
The biggest AI newsletter in the World
Get AI articles in your inbox
Technical curation on models, agents and coding tools. No spam, unsubscribe anytime.
In this article you will see:
- The published score for Kimi K3.1 Pro, Claude Opus 5.5 and GPT-6 Astra.
- How Moonshot describes the evaluation.
- What this result does not allow us to conclude.
Kimi K3.1 Pro x Claude Opus 5.5 on Terminal-Bench 4.0
Terminal-Bench evaluates agents that execute terminal tasks. Moonshot says it tested Kimi K3.1 Pro with benchmark version 4.0 and published the results in the official model announcement.
Performance on the benchmark
| Model | Terminal-Bench 4.0 |
|---|---|
| Kimi K3.1 Pro | 65.7% |
| Claude Opus 5.5 | 66.4% |
| GPT-6 Astra | 58.2% |
Kimi's score is close to Opus 5.5 and above the figure published for GPT-6 Astra. These are results released by Moonshot, not an independent evaluation done by bridgecode.
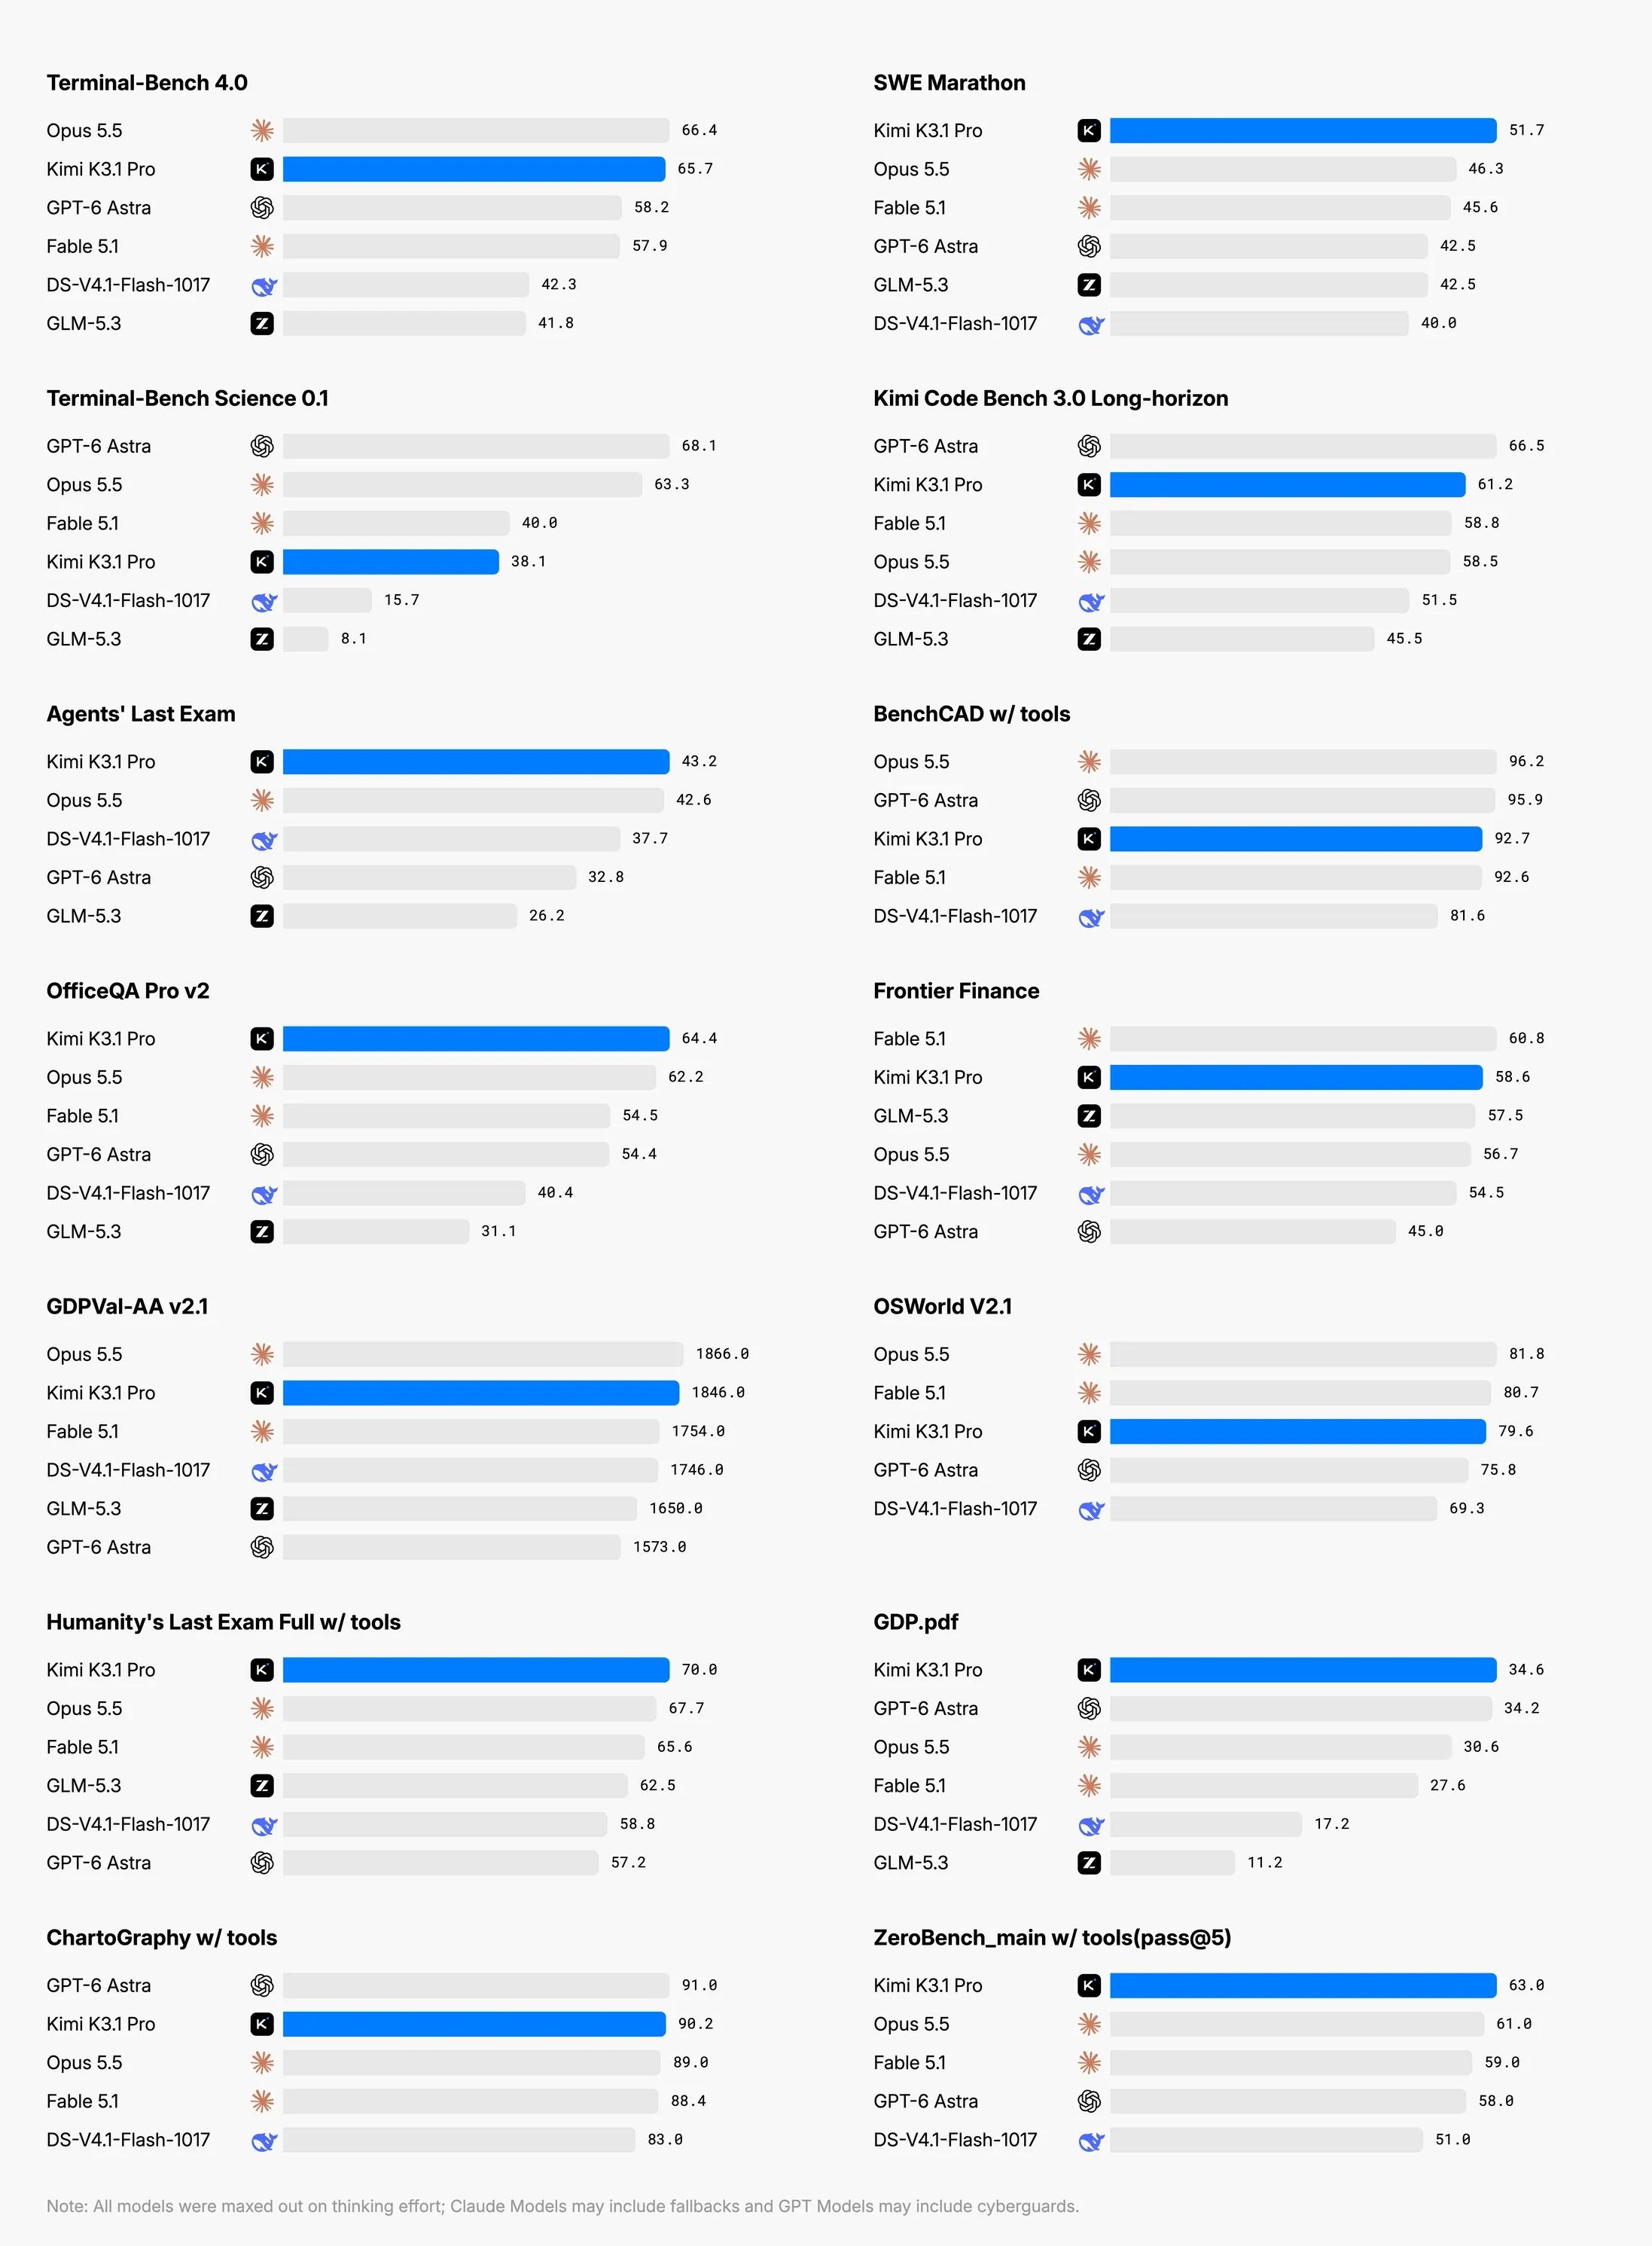
Image: Moonshot AI.
Method and test context
The announcement links the result to Terminal-Bench 4.0 and the agent workflow used by the team. Comparing scores requires checking the benchmark version, configuration and date of each run.
What the Kimi K3.1 Pro launch includes
Moonshot presents the variants Kimi K3.1 Pro and Kimi K3.1 Pro Highspeed and reports a context of up to 1 million tokens. The page says access started via Kimi Code.
To compare with another agent study, see the consistency evaluation of Qwen3.8-27B on ThinkingBox-Bench. Those who want to explore local options can consult the guide to open source assistants for programming.
What the Kimi K3.1 Pro score does not prove
The difference on Terminal-Bench does not determine which model will be better across every repository or workflow. The result depends on the tasks, tools and conditions used in the evaluation.
Moonshot also states that the technical report and weights would be published later. Therefore, this page does not confirm that those files are already available.
Frequently asked questions about Kimi K3.1 Pro on Terminal-Bench 4.0
What was Kimi K3.1 Pro's score on Terminal-Bench 4.0?
Moonshot reported 65.7% for Kimi K3.1 Pro on Terminal-Bench 4.0.
Did Kimi K3.1 Pro beat Claude Opus 5.5 in this test?
No. Moonshot's publication lists 66.4% for Claude Opus 5.5 and 65.7% for Kimi K3.1 Pro.
Where did Moonshot make Kimi K3.1 Pro available?
The launch page indicates access via Kimi Code. The announcement also presents the Kimi K3.1 Pro Highspeed variant.
Does the score prove Kimi K3.1 Pro is the best coding model?
No. The number refers to Terminal-Bench 4.0 and the test parameters described by Moonshot, not to all types of programming tasks.
How to choose between Kimi K3.1 Pro and Claude Opus 5.5
If the only criterion is the result published on Terminal-Bench 4.0, Opus 5.5 appears a little higher. To decide for a real project, compare the models on the same task, with the same tools and review criteria.
Kimi K3.1 Pro alone solves one task. An agent squad can handle the whole project, and you can build your agent team on bridgecode.
Source: Moonshot AI
Tags:#Kimi#Moonshot AI#Terminal-Bench#benchmarks#agentes de código
Developer and creator of bridgecode, an agentic development environment for orchestrating squads of AI agents. Helps people going from vibe coding to professional development move from idea to shipped product.
Related articles
Benchmarks
Inkling 2 Small drops 316 swear words in benchmarks: what this reveals
Inkling 2 Small dropped 316 swear words across 2,655 benchmark runs. What this reveals about reasoning loops and how we read benchmarks.
6 min
Benchmarks
Co-Design Bench: code agents get 26% of real world tasks right
Researchers built a code agent benchmark based on real user requests. Even the best model fully completes only 26.4% of tasks. See the numbers.
7 min

Benchmarks
Construction AI Leaderboard: Claude Opus 5.5 leads in 5 axes
ONESTRUCTION published on November 7, 2026 a ranking of 20 AI models across five real world construction work axes. Claude Opus 5.5 led with 73.7 points.
6 min