
On October 25, 2026, Nanbeige updated the card for Nanbeige4.3-33B. The latest revision, at 11:11 UTC, is in the official history and includes code, agent and reasoning benchmarks.

Nanbeige4.3-33B: agent benchmark results
The card updated on October 25 compares four models on agent tests, with results from the Nanbeige team itself and limitations in the evaluation.

Marcelo Santiago
Criador do bridgecode
The biggest AI newsletter in the World
Get AI articles in your inbox
Technical curation on models, agents and coding tools. No spam, unsubscribe anytime.
The numbers are an evaluation by the team itself. The card compares four models and reports the same harness and the same hyperparameters for each test, with the highest reasoning level.
In this article you will see:
- which models are in the comparison
- results on six code and agent tests
- limits and divergences in the published data
O que a equipe Nanbeige comparou
The four models are Nanbeige4.3-33B, Qwen3.8-27B, Muse-Glimmer-30B and Gemma4-31B, all in the range close to 30 billion parameters, according to the model card.
A benchmark is an evaluation with defined tasks and criteria. The harness brings together the instructions, tools and rules used to run the tests.
The team states that it used the same hyperparameters and the same harness per benchmark and that it tested all models at the highest reasoning level. The table is a cut of the team’s evaluation, not a global ranking of all models.
Resultados do Nanbeige4.3-33B em testes de agentes
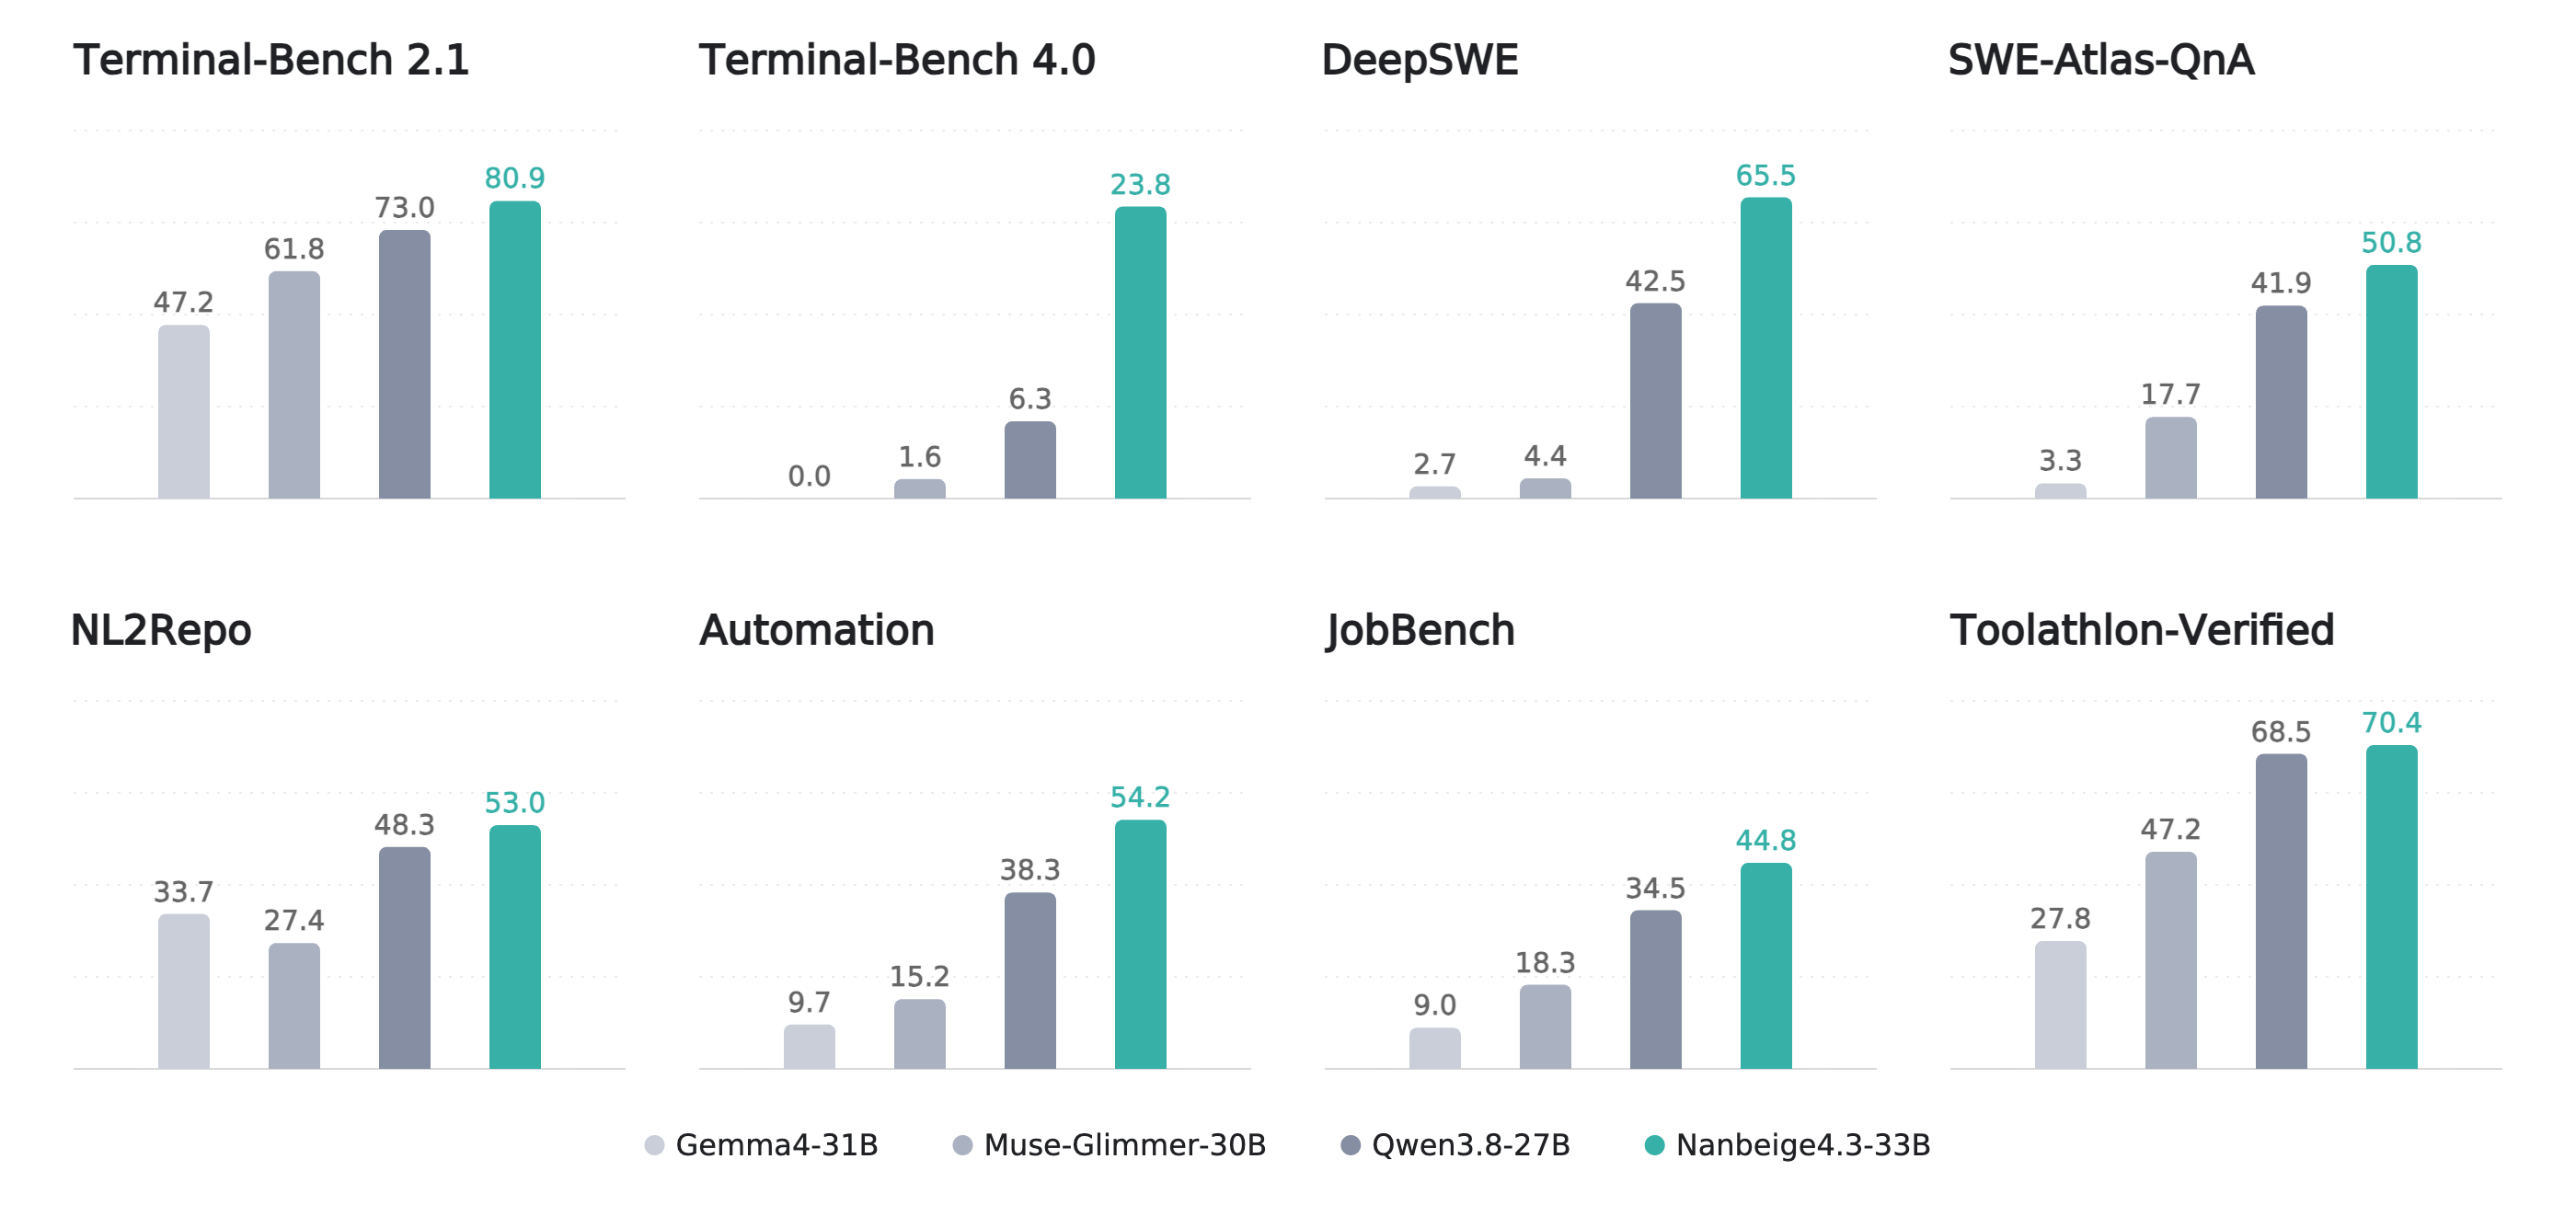
Credit: Nanbeige on Hugging Face.
The chart and the card table diverge on two values. To avoid picking data without confirmation, the table below shows six tests where both parts agree.
| Benchmark | Nanbeige4.3-33B | Qwen3.8-27B | Muse-Glimmer-30B | Gemma4-31B |
|---|---|---|---|---|
| Terminal-Bench 2.1 | 80.9 | 73.0 | 61.8 | 47.2 |
| Terminal-Bench 4.0 | 23.8 | 6.3 | 1.6 | 0.0 |
| DeepSWE | 65.5 | 42.5 | 4.4 | 2.7 |
| SWE-Atlas-QnA | 50.8 | 41.9 | 17.7 | 3.3 |
| Automation Bench | 54.2 | 38.3 | 15.2 | 9.7 |
| Toolathlon-Verified | 70.4 | 68.5 | 47.2 | 27.8 |
In the same card, the value of Gemma4-31B on NL2Repo appears as 33.7 in the chart and 33.8 in the table. For Muse-Glimmer-30B on JobBench, the chart shows 18.3 and the table 16.6.
The documentation states that Terminal-Bench 2.1 uses Terminus 2. Terminal-Bench 4.0 and DeepSWE use mini-swe-agent v2.4.6. The setup is part of reading the results.
To see other tests, compare the result of Kimi K3.1 Pro on Terminal-Bench 4.0 and the evaluation of Qwen3.8-27B on ThinkingBox-Bench.
O que os resultados do Nanbeige4.3-33B não provam
The numbers come from the evaluation published by the Nanbeige team itself and cover four models chosen for this comparison. They do not replace independent validation nor show which model will be better on every programming task.
The results serve as a signal for your own tests. Before choosing, check the version, instructions, tools and harness used in each benchmark.
Frequently asked questions about Nanbeige4.3-33B results
Which models were compared in the Nanbeige4.3-33B card?
The team compared Nanbeige4.3-33B, Qwen3.8-27B, Muse-Glimmer-30B and Gemma4-31B on code, agent and reasoning benchmarks.
What was Nanbeige4.3-33B's result on Terminal-Bench 4.0?
The card reports 23.8 for Nanbeige4.3-33B, versus 6.3 for Qwen3.8-27B, 1.6 for Muse-Glimmer-30B and 0.0 for Gemma4-31B. The team states mini-swe-agent v2.4.6 for this test.
Were the Nanbeige4.3-33B benchmarks validated by third parties?
The card presents an evaluation done by the Nanbeige team. The page does not state that the results were reproduced or audited independently.
Why do Nanbeige's chart and table diverge?
The card shows 33.7 in the chart and 33.8 in the table for Gemma4-31B on NL2Repo. For Muse-Glimmer-30B on JobBench, it shows 18.3 in the chart and 16.6 in the table, without explaining the differences.
Which harness was used on Terminal-Bench 4.0?
Nanbeige states mini-swe-agent v2.4.6 for Terminal-Bench 4.0 and DeepSWE. For Terminal-Bench 2.1, it states the Terminus 2 harness.
O que a comparação da Nanbeige permite concluir
The card brings together results on code, tool use and other agent tasks. It also makes explicit configuration differences between tests.
The two divergences between the chart and the table reinforce the importance of checking the data before drawing a conclusion.
From draft to finished product: split the work among specialist agents and track each step on bridgecode.
Source: Nanbeige on Hugging Face
Tags:#Nanbeige#Nanbeige4.3-33B#benchmarks#agentes de código#Terminal-Bench#modelos de IA
Developer and creator of bridgecode, an agentic development environment for orchestrating squads of AI agents. Helps people going from vibe coding to professional development move from idea to shipped product.
Related articles
Benchmarks
Inkling 2 Small drops 316 swear words in benchmarks: what this reveals
Inkling 2 Small dropped 316 swear words across 2,655 benchmark runs. What this reveals about reasoning loops and how we read benchmarks.
6 min

Benchmarks
Construction AI Leaderboard: Claude Opus 5.5 leads in 5 axes
ONESTRUCTION published on November 7, 2026 a ranking of 20 AI models across five real world construction work axes. Claude Opus 5.5 led with 73.7 points.
6 min
Benchmarks
Co-Design Bench: code agents get 26% of real world tasks right
Researchers built a code agent benchmark based on real user requests. Even the best model fully completes only 26.4% of tasks. See the numbers.
7 min