
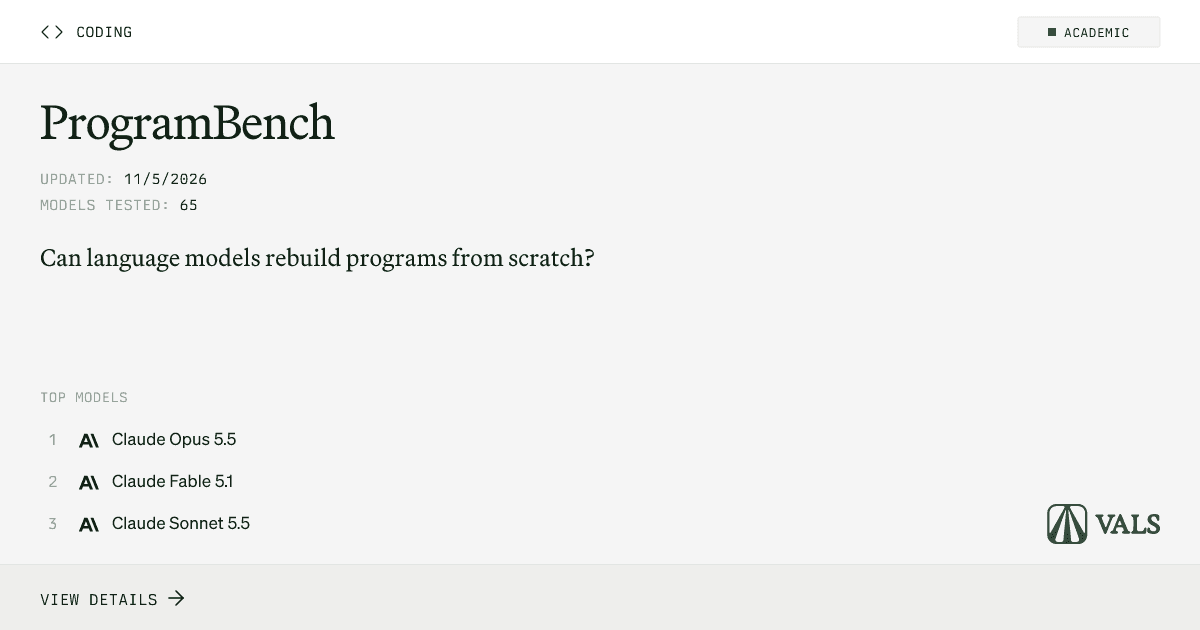
Vals AI published on November 5, 2026 a new round of ProgramBench, a benchmark that asks whether AI models can reconstruct command line programs from scratch. The short answer is: the best reach 18.5% accuracy, and most are well below that.
Benchmarks5 min
ProgramBench: Can AI Rebuild Programs From Scratch?
ProgramBench tests whether AI models can reconstruct command line programs from a binary and a specification. Claude Opus 5.5 leads with 18.50%.

Marcelo Santiago
Criador do bridgecode
The biggest AI newsletter in the World
Get AI articles in your inbox
Technical curation on models, agents and coding tools. No spam, unsubscribe anytime.
ProgramBench does not test whether the model knows the source code. It delivers a compiled binary and a behavioral specification, and asks for a clean implementation that compiles and passes the hidden tests. It is a reverse engineering test with programmatic verification, not a memory test.
In this article you will see:
- What ProgramBench asks the model to do.
- How the evaluation works in practice, steps, limits, and pass criteria.
- The official ranking from November 5, 2026 and what the numbers show.
- Why this benchmark matters for people who use code agents.
What is ProgramBench
ProgramBench is a code benchmark that evaluates whether a model can reconstruct a command line program from an executable binary and a behavior specification. Each task delivers the compiled binary and the description of what the program should do. The model needs to produce source code that compiles and reproduces the original behavior on the hidden tests.
The idea is to measure engineering ability, not recall. The model has no access to the internet, code repositories or decompilers. It can inspect the binary and run the executable, but it cannot reuse the binary or use binary analysis tools. The binary is executable only.
This differentiates ProgramBench from benchmarks like SWE-bench Pro, which starts from an existing repository and asks for a patch. Here there is no starting code: the model reconstructs from scratch.
How the evaluation works
Vals AI evaluates models on 200 public ProgramBench tasks. Each task provides a compiled program and the behavioral specification. The agent receives a bash terminal, an offline sandbox and the benchmark's standard prompt. It can inspect the delivered files and run the executable, but it cannot use the internet, consult package registries, wrap the provided binary, reuse object files or use decompilers, disassemblers, tracing or instrumentation.
The submission contains source code files and a build script. Vals compiles once and evaluates each hidden test branch in a new container created from the compiled image. The agent has up to 1,000 steps, a 6 hour wall clock limit and a 180 second timeout per action. Tool output is truncated to 10,000 characters at the ends.
A branch passes if the code compiles, the behavior reproduces the original and the hidden tests pass. There is no partial credit for explanation: either the implementation works, or it does not.
The official ranking from November 5, 2026
Vals tested 65 models on ProgramBench. Claude Opus 5.5 leads with 18.50% accuracy, followed by Claude Fable 5.1 with 7.00% and Claude Sonnet 5.5 with 6.50%. Most models are below 5%.
| Position | Model | Accuracy |
|---|---|---|
| 1 | Claude Opus 5.5 | 18.50% |
| 2 | Claude Fable 5.1 | 7.00% |
| 3 | Claude Sonnet 5.5 | 6.50% |
The gap between first and second is large: more than 11 percentage points. This shows that reconstructing a program from a binary is still a rare task, even for frontier models.
Vals also compares models on cost and latency per task. Claude Opus 5.5 costs more per attempt, but it is the only one that gets close to one in every five programs correct.
Why this benchmark matters
ProgramBench measures a capability that patch benchmarks do not capture: the ability to understand a system's behavior without starting code. This is useful in three real world scenarios.
First, reverse engineering and auditing: when you receive a third party binary and need to understand what it does. Second, recovery of legacy systems without source code. Third, validation of code agents that need to operate in environments where no repository is available.
The 18.5% result is also a reminder of a limit. Even the best model is wrong in more than 80% of cases. For anyone using code agents day to day, this reinforces the need for human review and testing, as discussed in the analysis of SnowPR in real repositories.
Frequently asked questions about the ProgramBench
What is ProgramBench?
It is a benchmark that evaluates whether AI models can reconstruct command line programs from a compiled binary and a behavioral specification, producing code that compiles and passes hidden tests.
Which model leads ProgramBench?
As of November 5, 2026, Claude Opus 5.5 was leading with 18.50%, followed by Claude Fable 5.1 with 7.00% and Claude Sonnet 5.5 with 6.50%.
Does ProgramBench start from an existing repository?
No. The model receives a binary and a specification, and must produce code from scratch. There is no starting repository and no internet access.
What are the time and step limits?
Each agent has up to 1,000 steps, 6 hours of wall clock time and 180 seconds per action. The code must compile and pass hidden tests in fresh containers.
How many tasks does ProgramBench have?
Vals AI evaluates 200 public tasks. Each task asks for the reconstruction of a command line program from the binary and the specification.
Conclusion: a capability benchmark, not a memory test
ProgramBench is one of the few benchmarks that tests whether a model truly understands software. The numbers from November 5, 2026 show that rebuilding a program from a binary is hard even for the strongest models. Follow the official leaderboard to see how the numbers change with new models.
An agent squad can split analysis, implementation and review, and that is what you coordinate on bridgecode.
Source: Vals AI
Tags:#benchmark#programbench#vals-ai#codigo#agentes
Developer and creator of bridgecode, an agentic development environment for orchestrating squads of AI agents. Helps people going from vibe coding to professional development move from idea to shipped product.
Related articles
Benchmarks
Vibe Code Bench: Can AI Build a Web App From Scratch?
Vibe Code Bench tests whether AI models can build complete web applications from a description. Claude Sonnet 5.5 on OpenHands leads with 92.39%.
5 min
Benchmarks
SRE Bench: Can AI Reverse Engineer Binaries?
SRE Bench tests whether AI agents can reverse engineer binaries without source code. GPT-6 Astra leads with 56.87%.
5 min
Benchmarks
CyberBench: Can AI find security bugs?
CyberBench tests whether AI agents can find security flaws in code and produce patches. Wonder from Meta leads with 80.36%.
5 min