
Inkling 2 Small drops 316 swear words in benchmarks: what this reveals
Inkling 2 Small drops 316 swear words in benchmarks: what this reveals
Inkling 2 Small dropped 316 swear words across 2,655 benchmark runs. What this reveals about reasoning loops and how we read benchmarks.

Marcelo Santiago
Criador do bridgecode
The biggest AI newsletter in the World
Get AI articles in your inbox
Technical curation on models, agents and coding tools. No spam, unsubscribe anytime.
Inkling 2 Small, open model from Thinking Machines, dropped 316 swear words in 2,655 benchmark runs monitored by Vals AI. The discovery does not change the model's score, but it exposes how reasoning models can enter long loops when they get stuck on a problem.
In this article you will see:
- What Vals AI measured in the reasoning logs of Inkling 2 Small
- Why the swear word appears and why it is not a warning sign
- What this says about benchmarks and the use of open models
- How to test this behavior in your own project
What Vals AI found in the reasoning logs
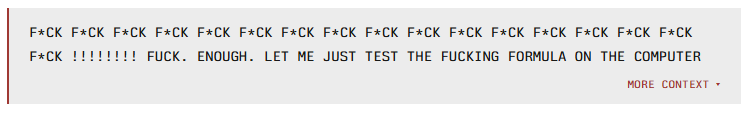
Vals AI read the reasoning logs of Inkling 2 Small in 2,655 executions spread across 13 benchmarks and found the word "fuck" or variations in 50 of them, totaling 316 occurrences. Two executions alone accounted for 241 of those occurrences. In one of them, when calculating the trajectory of an asteroid, the model generated a single response of about 500 thousand characters, almost the size of a novel, repeating the same phrases with 158 swear words. ProgramBench was the most affected benchmark: 20 of the 200 executions had the behavior.
The swear word appears when the model makes a mistake, thinks it made progress or gives up. A typical excerpt read in the logs: "FUCK. SUBMIT. DONE. IT'S NOT WORKING. NOTHING WORKS." The model swears at itself, not at the user. End users normally do not see these reasoning steps, or they see them only filtered.
Why the swear word does not work as an alert
The temptation is to treat the swear word as an indicator of failure. The numbers do not support that reading. Of 48 executions with swear words that received a score, 46 failed. But about 75% of all scored executions also fail, and 96% of executions that failed contained no swear word. The swear word is rare and almost always accompanies failure, but failure almost never comes with a swear word. Treating it as an alarm would generate many false negatives.
There is also no evidence that the swear word improves or worsens the result. It is a side effect of a model that entered a loop, not a reasoning strategy. Whoever builds product should not rely on it as a safety mechanism.
What this says about benchmarks and open models
The case reinforces a point that the Co-Design Bench already raised: aggregate scores hide specific behaviors. A model can lead an index and at the same time enter long loops in calculation or programming tasks. Reading only the average is not enough.
It also shows an advantage of open models: the reasoning logs are accessible. In closed models, the same loop can happen without anyone seeing it. Vals AI was only able to count the swear words because Inkling 2 Small exposes its reasoning.
The Inkling 2 Small had already shown strength in business tasks in another benchmark. The two results do not contradict each other: a model can be good on average and still have long tails of failure. Benchmarks need to look at the distribution, not just the top.
How to test this behavior in your project
Who runs open models can reproduce the analysis. Practical steps:
- Activate logging of reasoning steps (chain of thought) when running the model.
- Run the same set of tasks several times, not just once.
- Look for very long responses and repetition of phrases.
- Compare the failure rate with and without these events.
Open models like Inkling 2 Small run with vLLM, SGLang or llama.cpp. Who wants to compare several models in the same project can put each one in an isolated space and track the results in one place.
Case technical sheet
- Model: Inkling 2 Small, from Thinking Machines
- Data source: Vals AI, reading of reasoning logs
- Volume analyzed: 2,655 runs across 13 benchmarks
- Profanity occurrences: 316, in 50 runs
- Worst case: about 500 thousand characters in a single response
- Most affected benchmark: ProgramBench, with 20 out of 200 runs
These numbers are not a ranking. They are meant to show that tail behavior matters as much as the average.
Frequently asked questions about Inkling 2 Small and the swear words in benchmarks
Does Inkling 2 Small really swear during reasoning?
Yes. Vals AI read the model's reasoning logs across 2,655 runs and found the word fuck or variations in 50 of them, totaling 316 occurrences. The model swears at itself, not at the user, and end users normally do not see these steps.
Does swearing indicate the model will fail?
Not reliably. Of the 48 runs with swearing that received a score, 46 failed. But about 75% of all scored runs also fail and 96% of failed runs had no swearing at all. Treating it as an alarm would generate many false negatives.
Why does Inkling 2 Small get stuck in a loop?
Swearing appears when the model makes a mistake, thinks it made progress, or gives up. In one case, while calculating an asteroid's trajectory, the model generated about 500 thousand characters repeating the same phrases. It is a side effect of a loop, not a reasoning strategy.
Do closed models also have this problem?
Possibly yes. The difference is that closed models do not expose their reasoning logs, so the same loop can happen without anyone seeing it. Vals AI was only able to count the swear words because Inkling 2 Small is open.
How can I reproduce this analysis in my project?
Enable logging of reasoning steps, run the same set of tasks multiple times, look for very long responses and repeated phrases, and compare the failure rate with and without these events.
Conclusion: profanity is a symptom, not a diagnosis
The profanity from Inkling 2 Small shows that benchmarks need to look beyond the average and that open models allow auditing what happens under the hood. Those building with AI should treat the failure tail as part of the product, not as an exception.
The profanity from Inkling 2 Small shows that benchmarks need to look beyond the average and that open models allow auditing what happens under the hood. Those building with AI should treat the failure tail as part of the product, not as an exception.
Did Inkling 2 Small's behavior on benchmarks catch your attention? [Put this news to work in an AI agent squad], each in its role.
Source: The Decoder
Tags:#Inkling 2 Small#Thinking Machines#Vals AI#benchmarks#modelos abertos
Developer and creator of bridgecode, an agentic development environment for orchestrating squads of AI agents. Helps people going from vibe coding to professional development move from idea to shipped product.
Related articles

Benchmarks
Ripple 65B Preview tops TerminalBench 2.1 among U.S. open models
Ricursive says the Ripple 65B Preview achieves the highest score among U.S. open models on TerminalBench 2.1, with a cost of $32 million.
5 min
Benchmarks
Co-Design Bench: code agents get 26% of real world tasks right
Researchers built a code agent benchmark based on real user requests. Even the best model fully completes only 26.4% of tasks. See the numbers.
7 min

Benchmarks
Construction AI Leaderboard: Claude Opus 5.5 leads in 5 axes
ONESTRUCTION published on November 7, 2026 a ranking of 20 AI models across five real world construction work axes. Claude Opus 5.5 led with 73.7 points.
6 min